Image
NCC presenting the success story
Turkish National Science e-Infrastructure (TRUBA), operating under Turkish Academic Network and Information Center (TUBITAK ULAKBIM) is the coordinator of NCC Türkiye. Middle East Technical University (METU), Sabancı University (SU), and Istanbul Technical University (ITU) National Center for High-Performance Computing (UHeM) are the third parties of the NCC.
While METU is a public university based in Ankara, SU is a privately-funded university in Istanbul. ITU UHeM, also based in Istanbul, provides supercomputing and data storage services to academic and industrial users. Our competencies include High-Performance Computing (HPC), High-Performance Data Analytics (HPDA), Artificial Intelligence (AI), CUDA, Materials Science, Computational Fluid Dynamics (CFD), and several other fields. The particular third-party presenting this success story is SU.
 .

Industrial organisations involved
Erste located in Ankara, is a software engineering SME created in 2017, focusing on international R&D projects. It has a wide range of expertise in mobile-device management, predictive maintenance, digital twins, Internet of Things (IoT)-based intelligent port management, smart-software-powered manufacturing environments, blockchain-based ID management, etc. Sample projects Erste was involved in can be seen at https://www.ersteyazilim.com/en/projects-products-and-services/.

Technical/scientific Challenge
Although state-of-the-art speech-to-text models work well in English, they do not have the same performance for most of the other languages. Fine-tuning these models can be a solution, and using HPC systems for this purpose is the most cost-efficient solution. Erste requires the NCC’s consultancy to get support in training and using large-scale models for speech-to-text transcription in Turkish. The developed tools will be utilized in an international ITEA project called InnoSale (https://www.innosale.eu/), which focuses on advancing state-of-the-art technology in the retail industry.
Solution
Despite Erste's prior experience with a Proof of Concept study (PoC) using HPC resources for training traditional ML models, the company lacked of expertise on large-scale models and how to work with them. EuroCC's training sessions and TRUBA User Documents proved to be quite informative. The model chosen for fine-tuning was the largest Whisper model. Working with the HPC expert, memory-efficient training approaches,Parameter-Efficient Fine-Tuning (PEFT) and Low-Rank Adaptation (LoRA), were implemented. Thanks to the TRUBA HPC Centre’s help, the SLURM scripts that can work on multiple GPUs were prepared and the parameters for effective and efficient fine-tuning were set. We observed significant reductions in the character and word error rates of the pre-trained Whisper even after only 4-8 hours of training sessions.
Business impact
Training a large-scale ML model is a highly demanding task, requiring significant computational power and financial resources. Despite numerous research and efforts to alleviate these demands, access to the computation power remains inevitable. The TRUBA resources provided through the EuroCC-2 project have been instrumental in supplying the necessary computational capabilities to Erste. Moreover, using the NCC’s expertise on these models also enabled us to yield an effective training process with less time.
Ermetal (https://www.ermetal.com.tr/en), a large-scale manufacturing company in Türkiye and Erste’s use-case partner in InnoSale, shared meeting records manually transcribed by the engineers at Erste. This data is moved to TRUBA. Debug partitions available in the cluster were first utilized to rectify any potential errors and follow the error/loss behaviour. Additionally, public datasets have also been tested to enhance the model. The Whisper model obtained after selecting the memory-efficient training approaches, a careful selection of the training parameters, and submitting the job to the main cluster was tested for its usability in the InnoSale project, and significant improvements were observed. Erste has now expertise in using these scripts and will continue to improve the model with new data.
Benefits
Reduced training time with (1) multiple GPUs and (2) efficient training methods. Marked reduction in transcribed text errors, though further improvement is possible. Gain of expertise in large-scale model training. Model improvement and development of other cutting-edge tools using the acquired knowledge
Success story # Highlights
Technology: HPC, AI, speech to text, GPUs, LoRA, PEFT
Industry sector: Manufacturing
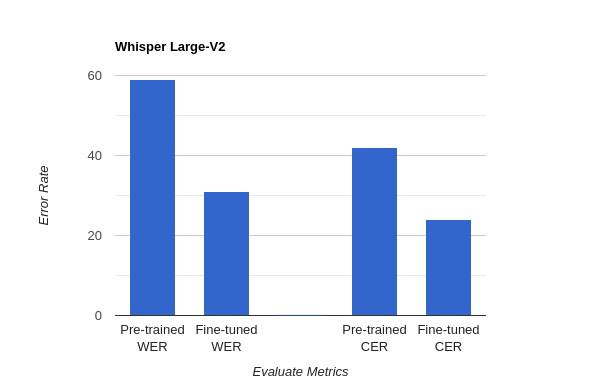
Figure 1: Word Error Rate and Character Error Rate for the downloaded, pre-trained Whisper model and the model fine-tuned with extra Turkish dataset.
Contact
Dr. Kamer Kaya, kaya@sabanciuniv.edu
This project has received funding from the European High-Performance Computing Joint Undertaking (JU) under grant agreement No 101101903. The JU receives support from the Digital Europe Programme and Germany, Bulgaria, Austria, Croatia, Cyprus, Czech Republic, Denmark, Estonia, Finland, Greece, Hungary, Ireland, Italy, Lithuania, Latvia, Poland, Portugal, Romania, Slovenia, Spain, Sweden, France, Netherlands, Belgium, Luxembourg, Slovakia, Norway, Türkiye, Republic of North Macedonia, Iceland, Montenegro, Serbia